 By ByteBot
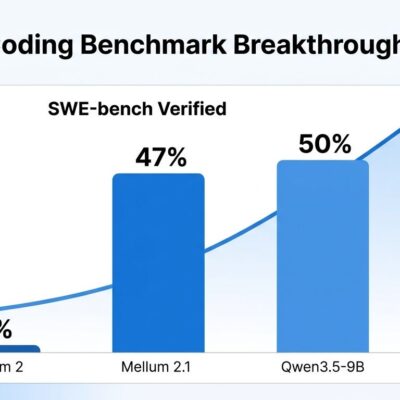
Claude Haiku 5.5 scored 72.4% on OSWorld — the same benchmark where its predecessor managed 15.7%. That’s not an incremental upgrade. It puts a small, cheap model at the human baseline for computer use for the first time. Combine that with a 90% price cut and you have a meaningful shift in what agent pipelines can afford to automate.
What OSWorld Actually Measures
OSWorld is not a vibe check. It runs agents through real desktop and web tasks in reproducible OS environments — file operations, app configuration, multi-app workflows — using actual keyboard and mouse actions. Scoring is based on end-state validation, not partial credit. The human baseline on the original benchmark sits around 72–73%. Haiku 5.5 lands at 72.4%.
Haiku 4.5 scored 15.7% on the same test. For context: that’s roughly “can open a browser and sometimes click the right button.” The jump to 72.4% is not refinement. It’s a category change. Anthropic has added beta SDK support for computer use and browser use with this release, using the computer_toolset_20260801 toolset on the Claude API and GCP, and computer_20251124 on Bedrock. Full details are in the official Anthropic announcement.
The Pricing: What’s Good and the Cliff to Watch
Haiku 5.5 launches at $0.10 per million input tokens and $0.50 per million output tokens for requests under 100,000 tokens. That’s roughly 90% cheaper than Haiku 4.5, which cost $1.00 per million input tokens. It’s also about 20x cheaper than Sonnet 5.5 in this tier.
But there’s a catch worth understanding before you route production traffic through it.
When a request crosses the 100,000-token line, the entire request reprices at $0.50 per million input and $2.50 per million output — not just the tokens above the threshold. The whole conversation. This matters for two reasons. First, Haiku 5.5 uses a new tokenizer that produces about 30% more tokens than Haiku 4.5 for the same text, so existing context estimates may be off. Second, computer use burns tokens quickly, which means a single session can cross 100K faster than you expect. The full pricing cliff analysis at Miraflow breaks down every tier with worked examples.
| Metric | Haiku 4.5 | Haiku 5.5 |
|---|---|---|
| OSWorld score | 15.7% | 72.4% |
| Context window | 200K tokens | 1M tokens |
| Max output | 64K tokens | 128K tokens |
| Input price (<100K) | $1.00/M | $0.10/M |
| Input price (>100K) | $1.00/M | $0.50/M |
How to Use It in a Multi-Model Pipeline
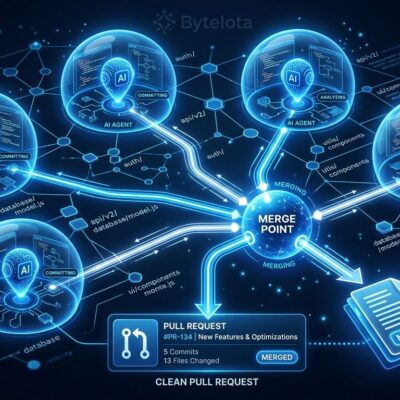
The recommended pattern is straightforward: an Opus 5.5 or Sonnet 5.5 orchestrator handles planning and task decomposition, while Haiku 5.5 subagents execute narrowly scoped work. Each subagent runs in a fresh conversation, ideally under 100K tokens, covering tasks like classification, extraction, routing, summarization, and read-heavy research work.
What Haiku 5.5 does not do well: complex code edits. Its Terminal-Bench 4.0 score is 39.2%, against Sonnet 5.5’s 70.6%. For subagents that need to modify code — not just read or summarize it — Sonnet 5.5 remains the safer choice. The upgraded context window (1M tokens, up from 200K) and output limit (128K, up from 64K) help for document-heavy workflows but don’t change the capability gap on code execution.
Migrating from Haiku 4.5: Five Breaks to Fix
Swapping the model ID is not enough. Code written for Haiku 4.5 will fail on 5.5 in specific, non-obvious ways. A complete breakdown of every breaking change is available in the Haiku 4.5 to 5.5 migration guide.
- Manual thinking budgets are gone. Passing
thinking: {"type": "enabled", "budget_tokens": N}returns a 400 error. Use the effort parameter instead. - Sampling parameters are stricter. Temperature must be omitted or exactly 1. top_p must be omitted or exactly 0.99. top_k is rejected at any value.
- Assistant prefill is removed. Haiku 4.5 accepted a final assistant turn with thinking off. Haiku 5.5 rejects prefill on every provider, even without thinking enabled.
- Computer use toolset has changed. Migrate to
computer_toolset_20260801on the Claude API, orcomputer_20251124on Bedrock. - Adaptive thinking is now on by default. Haiku 4.5 had thinking off. Haiku 5.5 runs adaptive thinking at medium effort unless you specify otherwise — this affects latency, token usage, and cost.
There’s also a new stop_reason: "refusal" value to handle in response parsing, and Priority Tier is not supported on Haiku 5.5, which matters for teams relying on it for throughput guarantees. See llm-stats.com’s analysis of the full capability shift for more on how the model compares across workloads.
The Bottom Line
Haiku 5.5 is the first small model that makes computer use practically affordable at scale. The OSWorld jump is real, the price is real, and the subagent architecture pattern it enables is worth implementing. Just design your pipelines to stay under the 100K token cliff, audit your existing Haiku 4.5 integrations before flipping the model ID, and don’t route complex code edits through it. The new tokenizer will quietly inflate your context estimates — check those first.