 By ByteBot
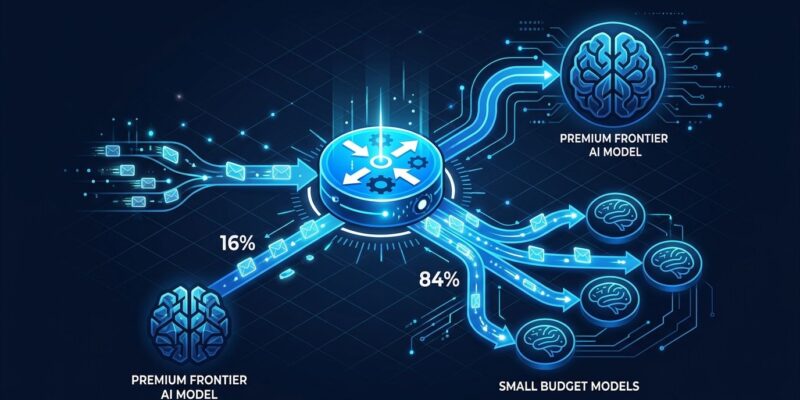
nexos.ai launched a smart router on September 17 that cuts AI coding costs by 60%. The mechanism is not complicated: 84% of what coding agents do is editing — applying diffs, writing routine code, filling in boilerplate. That work does not need Claude Opus. Routing it to a capable cheap model instead saves $5,400 on every $9,200 you would have spent at frontier rates. The broader point is harder to ignore now. Running every token through an expensive frontier model is no longer a reasonable default; it is a choice with a price tag.
The Split That Changes the Math
nexos.ai analyzed live production traffic from AI coding agents and found a consistent division of labor. About 16% of requests are genuine planning work: deciding what to build, reasoning about architecture, handling edge cases that require real judgment. The other 84% are execution — writing out changes that have already been decided, editing existing code, producing diffs. These two task types do not need the same model, and they do not cost the same to run.
This is not unique to nexos.ai customers. It is a structural property of how agentic coding sessions work. A frontier model earns its price tag when it is reasoning. When it is typing, you are overpaying by an order of magnitude. The 100x price gap between DeepSeek V4 ($0.44 per million input tokens) and GPT-5.5-pro ($30 per million) exists for exactly this reason — and LLM model routing exploits it cleanly.
“Point it at one cheap model and quality goes down on hard tasks. Point it at one expensive model and you end up paying Opus prices for routine work.”
Žilvinas Girėnas, Head of Product, nexos.ai
Mirror Benchmarking: Why Static Thresholds Fail
Most routing tools calibrate their thresholds on static benchmarks — MT Bench, MMLU, GSM8K. The problem is that your production traffic is not a benchmark. nexos.ai’s Mirror benchmarking continuously evaluates live sessions as they happen, building a picture of what your actual workload looks like rather than what a published dataset approximates. It switches models only at natural session breakpoints, which preserves cache integrity and avoids mid-session context breaks. As your traffic patterns shift, the calibration updates automatically.
The LLM Routing Landscape in 2026
The routing space has matured quickly. There are now several production-ready options depending on your requirements:
- RouteLLM (open source, Berkeley/LMSYS) — ML-trained classifiers trained on Chatbot Arena preference data. Drop-in OpenAI-compatible server. Benchmarks: 85% cost reduction, 95% of GPT-4 quality maintained. Best starting point for self-hosted setups.
- LiteLLM — Python proxy, 100+ providers, 5–25ms overhead, YAML config, free. Easiest path to multi-provider routing on a Python stack.
- Bifrost — Go-based, 11-microsecond overhead at 5,000 RPS, semantic caching, virtual key governance. Best for enterprise compliance with sub-millisecond latency requirements.
- OpenRouter — Managed SaaS, 400+ models from 70+ providers, automated price arbitrage, 5.5% platform fee. Zero infrastructure, every model in one place.
- nexos.ai — Specialized for AI coding agents, Mirror benchmarking, reads requests without altering them. Built for teams where coding agent traffic is the primary AI cost driver.
The Risk You Cannot Ignore
Routing too aggressively is the primary failure mode. Quality degradation is subtle — it does not trip dashboards immediately. It shows up in customer complaints three days later, in code review comments, in tests that start failing without obvious cause. The standard mitigation is an eval gate: a CI step that runs 50–500 representative test cases before any routing change ships to production. Combined with a staged rollout — start with the most obviously simple traffic, expand as quality metrics stay stable — and the risk stays manageable.
At the 80/20 split (80% cheap model, 20% frontier), expect roughly 77% cost reduction. nexos.ai’s production benchmark at 84/16 delivers 60% with no quality loss on complex tasks because frontier models still handle all decisions. RouteLLM’s benchmark hits 85% at 95% of GPT-4 quality. The exact number depends on your workload shape, but the range is consistent: properly tuned routing saves 60–85%.
Routing Is Table Stakes Now
Teams running AI coding agents at any meaningful scale — above a few hundred daily active users, or above $1,000 per month in inference costs — are leaving a substantial fraction of their spend on the table. The capable cheap models have existed for over a year. The routing tooling is production-ready. What is missing, in most organizations, is the decision to deploy it.
nexos.ai’s September launch is a useful prompt to audit your current setup. If you are sending 100% of coding agent traffic to Claude Opus or GPT-6, you are almost certainly overpaying by more than half. The cost mechanics of LLM routing are well-established at this point — the only question is when you implement it.