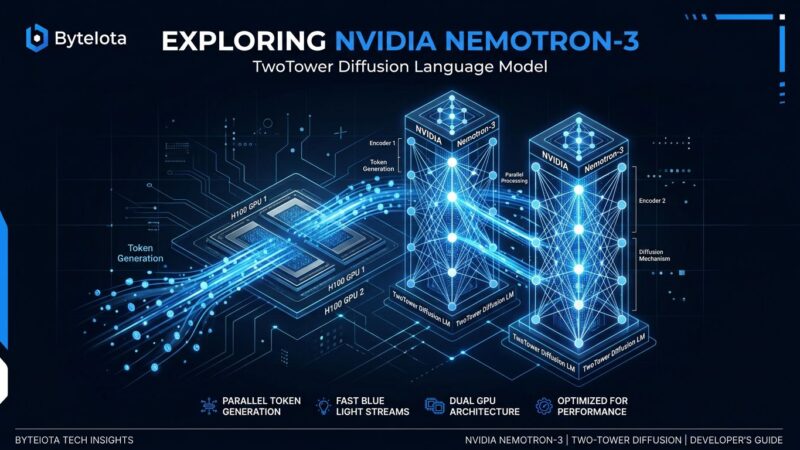
NVIDIA Nemotron TwoTower: 2.42x Faster LLM Inference
NVIDIA’s Nemotron-Labs-TwoTower delivers 2.42x faster LLM inference at 98.7% quality without retraining the base model. Here’s what it means for your inference stack.

AI coding tools, LLMs, agents, and AI-assisted development