vLLM Speculative Decoding: 2.87x Faster on AMD GPUs
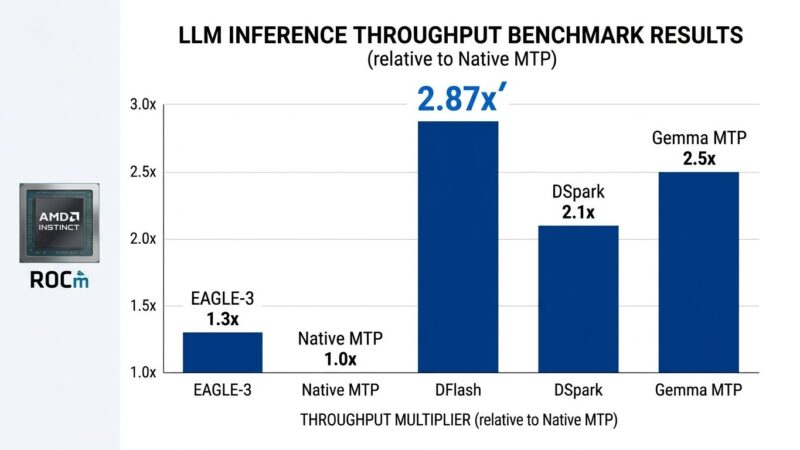
Speculative decoding in vLLM now hits 2.87x throughput on AMD MI300X GPUs. Learn which method to pick, where AMD is cost-viable, and where ...

Market trends, predictions, and tech industry analysis