 By ByteBot
Gimlet Labs closed a $300 million Series B on September 4 at a $3 billion valuation, led by Andreessen Horowitz. The headline number is large, but the investor list is what matters: Arm Holdings and Microsoft’s M12 joined the round alongside a16z, Sapphire Ventures, and Menlo. Two companies with chip-level skin in the game betting on software that routes AI inference away from pure-NVIDIA stacks. That is not a coincidence — it is the thesis.
What Gimlet Actually Builds
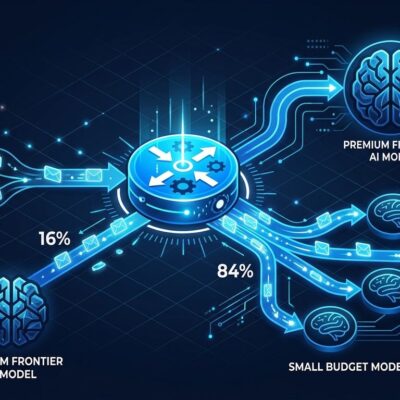
Gimlet builds what it calls a multi-silicon inference cloud: a platform that disaggregates AI model execution across heterogeneous hardware — GPUs, CPUs, Arm chips, Cerebras wafer-scale processors, d-Matrix dataflow units, and more — rather than running everything on identical NVIDIA accelerators. The company claims 3x to 10x faster inference for equivalent cost and power.
The core technique is prefill-decode disaggregation. When an LLM processes a request, it performs two computationally distinct operations: the prefill stage encodes your prompt and builds the KV cache (compute-heavy, GPU-friendly), and the decode stage generates tokens one at a time (memory-bandwidth-heavy, better suited to different hardware). Running both phases on the same GPU wastes resources. Separating them onto optimized silicon — and routing intelligently between them — is the efficiency gain Gimlet is selling. The company goes further than standard PD disaggregation, slicing models to execute across different architectures simultaneously.
Why Agentic AI Makes This Urgent
Agentic workloads are where this matters most. A single user request to an AI agent can involve dozens of inference calls: model invocation, tool calls, retrieval, verification loops, and more. Each call compounds latency. A 3x throughput gain at the inference layer multiplies across the entire pipeline. CEO Zain Asgar frames this as a timing play: “We’ve reached a turning point where inference is the dominant AI workload and the demand for tokens is explosive.”
The efficiency gap is real. Asgar has stated that current deployed GPU clusters run at only 15 to 30 percent utilization. That is not just waste — it is the market opportunity. When hardware runs that expensive in capital expenditure but that underutilized in practice, the routing layer that fixes it becomes worth building.
Reading the Investor List
Arm’s participation is not passive. Arm-based silicon — AWS Graviton, Azure Cobalt, Apple M-series — already runs production inference workloads. An orchestration layer that routes decode-phase workloads toward Arm chips is effectively a sales engine for Arm’s licensees. Arm investing in Gimlet is Arm investing in its own inference market share.
Microsoft’s M12 tells a similar story. Microsoft has built custom Maia AI chips and needs production-grade software to make them viable inside Azure. If Gimlet’s orchestration can make Maia chips competitive alongside NVIDIA GPUs in real workloads, that is Microsoft reducing NVIDIA dependence while improving Azure margins. Andreessen Horowitz general partner Raghu Raghuram put it plainly: “The answer isn’t just more infrastructure — it’s a better architecture.”
Who This Is For Right Now
Be clear-eyed about scope. According to its Series B announcement, Gimlet is targeting frontier AI labs and hyperscalers — one of the top three AI labs and one of the top three cloud providers are already customers, though neither is named. This is not a self-serve inference API for your next side project. Deployment is either through Gimlet Cloud (a managed service) or as software running inside a customer’s own datacenter. Both imply enterprise contracts.
The company plans to expand its serverless infrastructure by several hundred megawatts and move into custom inference hardware for deployments outside traditional data centers. Broader access is on the roadmap — it is not here yet.
The GPU Monoculture Is Cracking — Slowly
The honest read: the market thesis is credible, the backers are strategically aligned, and the technical problem is real. What is missing is public evidence of production scale. Gimlet has disclosed no revenue and no customer names. At $3 billion, this is a structural bet on heterogeneous inference becoming the default, not a validation that it already is. SiliconANGLE’s analysis of the round notes the company reports “billions of dollars’ worth of customer orders” — a metric that is harder to verify than ARR but still meaningful.
The conditions for this market shift are in place regardless. AMD ROCm is maturing. Cerebras is in production. Intel Gaudi 3 is deployed. Arm server chips are proliferating across major cloud providers. TechCrunch’s earlier reporting on Gimlet’s Series A noted the core challenge: “no chip yet does it all.” Six months and $300M later, Arm and Microsoft are betting that Gimlet’s software is the layer that makes heterogeneous inference actually work at scale. Watch this one.