 By ByteBot
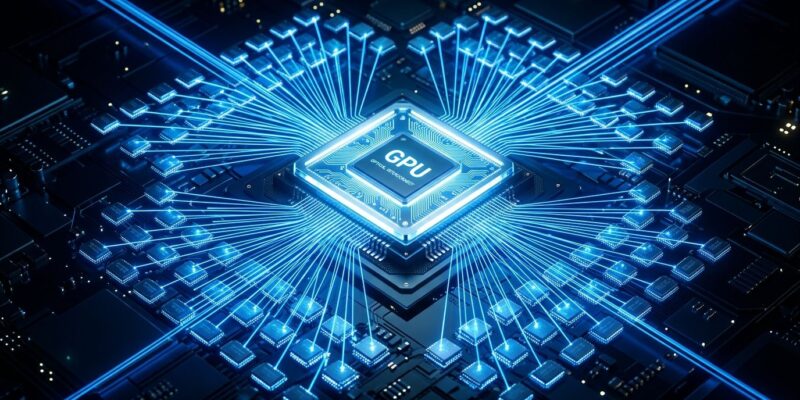
Every expensive AI API call you pay for is a memory problem wearing a compute costume. GPU cores sit idle waiting for data to arrive — not because the silicon is slow, but because copper wires can only reach so far. San Francisco startup Volantis just closed an $88 million Series A to replace those copper wires with laser beams, claiming their first system will connect a single GPU to 220 memory chips instead of the 8 it gets today.
Why Your GPU Is Mostly Waiting
GPU compute capacity has grown 25x since 2018. Memory bandwidth has grown 7x. That gap is the memory wall, and it is why throwing more TFLOPS at LLM inference does not actually make it faster. Language model inference is memory-bandwidth-bound for almost every production workload — the bottleneck is how fast weights can travel from memory to compute cores, not how fast the cores run once they have the data.
The numbers get worse with scale. A 70B-parameter model at FP16 precision consumes 140 GB of memory just for weights. An NVIDIA B200 has 192 GB total, leaving 52 GB for the KV cache. Serve 100 concurrent users on long contexts and that remaining 52 GB disappears fast. High-bandwidth memory (HBM) now represents 45% of a B200’s manufacturing cost, and the entire 2026 HBM supply from SK Hynix and Micron is already sold out. The memory wall is not an abstract concern — it is the reason GPU inventory is tight and inference margins are thin.
Copper Reaches 5mm. Light Reaches 200mm.
The physics of electrical interconnects limit how far copper can reliably carry data: roughly 2 to 5 millimeters. That is why current Nvidia GPUs top out at around 8 HBM chips — each one has to be physically stacked close to the die. Volantis replaces copper with vertical-cavity surface-emitting lasers (VCSELs), which can reach over 200 millimeters. That 40-100x increase in reach is how they get from 8 memory chips to 220.
The material choice is deliberate. Volantis uses gallium arsenide rather than indium phosphide, the material most photonic startups favor. China controls 70% of global indium phosphide supply, and InP wafer prices surged roughly 250% earlier this year. Gallium arsenide VCSELs, by contrast, are already manufactured at consumer scale — the same technology is in your iPhone’s Face ID sensor. Billions of units ship annually. That is a supply chain you can actually build a business on.
The A-1 System: Targets, Not Receipts
Volantis’s first product, the A-1, is a 15U datacenter appliance targeting 10 terabytes of memory capacity, 240 terabytes per second of bandwidth, and up to 10,000 tokens per second per user. The company claims it will deliver "15x better tokens per dollar than NVIDIA Rubin" and run models above 20 trillion parameters. First customer deliveries are scheduled for 2027.
Those are design targets. No independent customer has benchmarked the A-1. The chip has reportedly taped out — completed its design phase — but no volume production exists yet. The gap between a taped-out chip and a product shipping at datacenter scale is where hardware startups most often stumble.
The Team Has the Right Résumé
CEO Tapa Ghosh is a Thiel Fellow and YC W18 alum who previously founded semiconductor startup Vathys. CTO Roy Meade spent years at Micron specifically on HBM design. Co-founder Inderjit Singh is a former Nvidia engineer. The investor list includes Sam Altman, Jeff Dean, Naval Ravikant, and Alex Wang — but the most meaningful signal may be Dylan Patel of SemiAnalysis putting money in. Patel has been the most accurate public analyst on GPU supply chain and AI infrastructure economics for three years running. His participation suggests the technical bet is not obviously wrong.
The Series A was led by Lachy Groom and Abstract Ventures, with John Doerr, VXI Capital, Triatomic, and Susa Ventures participating. Total capital raised is $97 million.
What Developers Should Watch
If Volantis delivers in 2027, the practical consequence for developers is cheaper inference on large models — particularly for long-context workloads where KV cache pressure is the binding constraint. Inference providers who adopt A-1 would have access to far more memory per compute unit, which translates directly to lower cost per token.
If it does not deliver, the incumbents are not standing still. HBM4 is targeting 2 TB/s per stack, roughly double HBM3E. Lightmatter and Ayar Labs have raised $400–700 million each for their own photonic approaches. Kandou is making the case that advanced copper packaging can extend electrical interconnects far enough to remain competitive. The memory wall will get addressed by someone — Volantis just announced they want to be first, and have $88 million to try.