 By
OpenAI shipped a POST /v1/decisions endpoint into public beta on October 6. It takes your text or images, answers developer-defined questions, and returns typed verdicts — no prose, no parsing, no output token charges. If you have any classification pipeline running on the Responses API today, the math just changed.
The Classification Tax You’ve Been Paying
Every time you’ve used an LLM to classify something — route a support ticket, score a lead, flag a content violation — you’ve been paying output token charges for words you immediately discarded. The model writes “billing” or “high severity” and you strip everything else. OpenAI calls this out directly in the release: if your calls return three tokens of verdict, you were overpaying.
The Decisions API removes that overhead entirely. It doesn’t generate text. It evaluates your input against questions you define and returns structured answers. Input tokens only, at $0.10 per million.
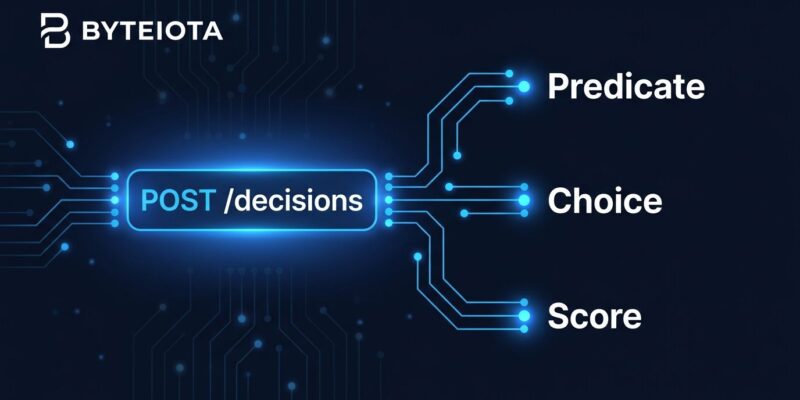
Three Answer Types
The API supports three question formats, and choosing the right one matters.
Predicate returns a probability between 0 and 1 for a binary condition. Ask “Does this image show visible product damage?” and you get back 0.87 — no interpretation layer needed.
Choice picks one option from a fixed, unordered set and includes a confidence score and full probability distribution across every option. This is your support routing, document classification, and agent tool-selection use case.
Score rates an input against ordered severity or quality levels and returns a probability-weighted average. A bug severity question with levels ranging from “Cosmetic” to “Fully blocked” might return 2.4 — landing between defined thresholds rather than forcing a discrete jump.
What a Real Request Looks Like
Here’s a Python example routing a support ticket:
from openai import OpenAI
client = OpenAI()

response = client.decisions.create(
    model="gpt-6-luna",
    input="I was charged twice last month",
    questions=[{
        "type": "choice",
        "name": "queue",
        "instructions": "Which support queue handles this?",
        "choices": [
            {"value": "billing",   "description": "Payments, charges, refunds."},
            {"value": "technical", "description": "Product bugs and outages."},
            {"value": "shipping",  "description": "Delivery and logistics."},
            {"value": "other",     "description": "Everything else."}
        ]
    }]
)

print(response.answers[0].choice)      # "billing"
print(response.answers[0].confidence)  # 0.93
You get back the winning choice and how confident the model is. No parsing. No regex. No hoping the model said “billing” and not “Billing Department.”
SDK minimums: Python 3.26.0+, JavaScript 7.30.0+. Check your versions before migrating.
Decisions API vs. Everything Else
The official docs give a clean decision rule: if the next line of your code is an if statement or switch on the model’s answer, you want the Decisions API. If you need the model to also generate explanatory text or extracted fields, use Structured Outputs. If the model needs to invoke a tool, use function calling.
On price, the picture is more complicated:
- Decisions API: $0.10/M input, $0 output
- Responses API (Luna): $0.10/M input, $0.50/M output
- Jev (text-only): $0.042/M input, $0 output — detailed cost breakdown here
For 1 million 500-token text classifications: Jev costs $42, Decisions API costs $50, Responses API costs around $70 with average output tokens. If you don’t need multimodal input or HIPAA compliance, Jev wins on price. If you need images or the compliance tier, Decisions API is the right tool.
The Catches
This is a public beta, and it shows in a few places.
Only gpt-6-luna is supported. No model choice, no swapping in something cheaper for bulk runs. That changes at GA — expected in late October or November — but for now you’re locked in.
Images must be base64 inline data URLs. If your pipeline fetches images from URLs at classification time, you’re adding a download and encode step before every request. Factor that into your latency budget.
Dependent questions require separate requests. If question 2 depends on the answer to question 1, you’re making two API calls. Independent questions can share a single request.
OpenAI claims “roughly 10x faster answers” versus the Responses API. There are no independent benchmarks supporting this. Test against your workload before committing architecture decisions to that number.
Confidence scores are not calibrated to your data. A 0.93 confidence doesn’t mean it’s wrong 7% of the time on your tickets. Run it against a labeled dataset and build your own thresholds before going to production.
Migration Path
Existing Responses API conversations cannot be ported directly. You’ll need to build a task-specific evidence payload — essentially reformatting your classification context into the Decisions API input structure. If you’re classifying document text, this is trivial. If you rely on conversation history for context, plan for the reconstruction work.
Verdict
If you’re running text classification with the Responses API, move to the Decisions API now. The structured response alone is worth it — the pricing delta is a bonus. If you’re on Jev and don’t need images, stay put until you can benchmark both. If you’re still building prompt-based classifiers from scratch, stop: a purpose-built classification endpoint at $0.10/M exists and it works.
GA pricing and multi-model support are coming. Lock in the beta behavior while it’s free to experiment, but build your thresholds on labeled data before you depend on confidence scores in production.