 By ByteBot
Mistral just shipped Le Chonk — a 1-trillion-parameter open-weight model that beats GPT-6 Astra on visual grounding, tops every open model on cybersecurity benchmarks, and has weights scheduled for end of October. The catch: license terms are still unpublished, the preview context window is half what’s advertised, and you’ll need eight H200s to run it locally. According to Mistral’s official announcement, this is the first frontier-class model trained entirely on European infrastructure — and the only open-weight option that competes in a domain where every closed model refuses to play.
The Architecture That Makes Self-Hosting Complicated
Mistral Large 4 uses a Mixture-of-Experts architecture with 1.05 trillion total parameters and approximately 49–52 billion active per token. That distinction matters more than the headline number. Active parameters drive inference compute — so ML4 processes tokens at roughly the cost of a 50B dense model. But total parameters determine VRAM requirements, because the full weight matrix lives in memory regardless of how much fires per forward pass.
At 4-bit quantization (the most likely shipping precision), weights alone consume around 525GB. Add activations and runtime overhead and you need roughly 630GB of GPU memory. The minimum viable single-node config is eight H100 80GB cards — with essentially no margin. Eight H200s is the comfortable option. BF16 full precision is multi-node territory at 2.5TB+. For a detailed breakdown of GPU configurations, see the hardware requirements guide from Yotta Labs.
Until Mistral publishes the actual checkpoint precision at weights release, all of these numbers are estimates. That is the first thing to verify when the weights land.
The Cybersecurity Benchmark Is the Real Differentiator
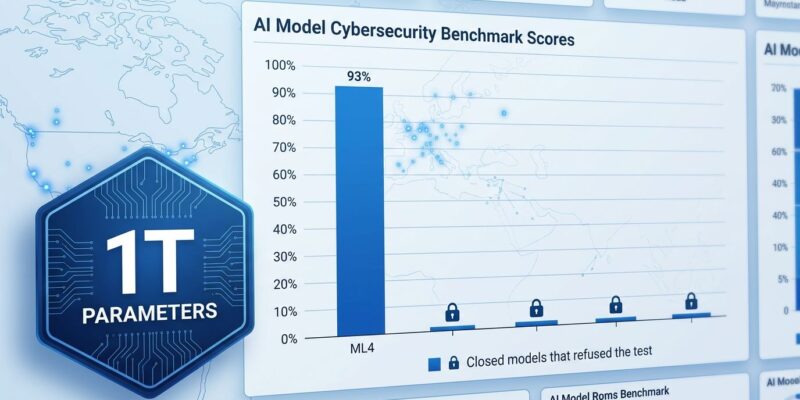
ML4 scores 93% on Cybench — 40 CTF-style capture-the-flag security challenges — and 82% on CyberGym-E2E, which tests whether a model can reproduce and patch known vulnerabilities. Both scores place it in the global top five on the Artificial Analysis Cyber Index.
The comparison that makes these numbers meaningful: Claude Opus 5.5 and GPT-6 score near zero on the same benchmarks. Not because they lack capability, but because they refuse the tasks. Models trained to decline offensive-security-style prompts are functionally useless for security research, red-teaming, and vulnerability analysis. ML4 does not refuse. For teams building penetration testing automation, exploit analysis tooling, or security agent workflows, this is not a marginal improvement — it is the difference between a model that works and one that does not.
On coding, ML4 posts 61.7% on DeepSWE v1.1 and a 49.8% Coding Agent Index score, edging out DeepSeek V4 Pro. It trails Kimi K3 and GLM-5.3 (both at 69% on the public leaderboard), though Mistral’s internal benchmarks dispute that gap. Take the coding numbers as competitive, not dominant.
The API Is Live — With One Asterisk
The preview is available now on Mistral Studio, OpenRouter, and Vercel AI Gateway. Pricing is currently at 50% discount with no stated end date: $0.68/M input tokens, $2.09/M output. List price is $1.36/$4.18. That puts ML4 below GLM-5.3 at $1.40/$4.40 and well below Kimi K3 at $3/$15 per million.
The asterisk: the preview maxes out at 524K tokens of context, not the advertised 1M. Mistral has not acknowledged this discrepancy publicly. If your workflow depends on long-context processing, test the actual limits before building against it.
curl https://api.mistral.ai/v1/chat/completions \
  -H "Authorization: Bearer $MISTRAL_API_KEY" \
  -d '{"model": "mistral-large-4", "reasoning_effort": "high"}'
The reasoning_effort parameter accepts "none" or "high". High effort increases output quality at the cost of latency and token count. Worth noting: ML4 produces 2.5x the median output tokens of comparable models. Verbose by default — factor that into your cost projections.
The License Regression You Should Flag Now
Mistral Large 3 shipped under Apache 2.0. Commercial use allowed. Fine-tuning allowed. Redistribution allowed. No revenue thresholds. Large 4 ships under a custom license whose terms have not been published yet.
This follows the same pattern as Large 2, which had commercial use restrictions. That is not speculation — it is Mistral’s own track record. The license implications for startups and enterprises building on open-weight models deserve legal review before you commit to production infrastructure. When the weights drop, get the license text to your team immediately and answer four questions: Is there a revenue or user threshold? Can you fine-tune and keep the derivative private? Can a third party host it on your behalf? Does the acceptable-use list cover your industry?
Until those answers exist, you cannot plan a production deployment based on self-hosted ML4. The preview API is fair game. Long-term infrastructure bets are not.
What to Do Before End of October
- Run your actual workloads against the preview API now — the 50% discount makes this cheap, and the performance signal will be real
- Identify your GPU config: 8x H200 is the pragmatic self-host option for 4-bit; verify pricing now
- Pre-allocate fast local storage: plan for 1–4TB NVMe for checkpoint storage and serving
- Check vLLM, SGLang, and llama.cpp compatibility on release day — none have confirmed ML4 support yet
- Read the license before committing architecture decisions
The “Le Chonk” nickname is self-aware. Mistral knows this is a large, complicated, and in some ways over-hyped release. But the cybersecurity benchmark story is genuine. If your work involves security tooling and you have been stuck using closed models that refuse every interesting task, the end of October has a date worth circling.
For everyone else: it is a strong open-weight frontier model with an unresolved license and hardware requirements that put self-hosting out of reach for most teams. The API is worth testing today.