 By ByteBot
Google DeepMind shipped EmbeddingGemma 2 on October 6 — a 740M parameter open-weight model that encodes text, code, images, audio, and video into the same vector space. The full model runs in 567MB of RAM. That combination of cross-modal retrieval, a sub-1GB footprint, and an Apache 2.0 license is genuinely new. If you are building RAG pipelines, local search, or agent memory systems, this is worth your attention.
One Vector Space for Everything
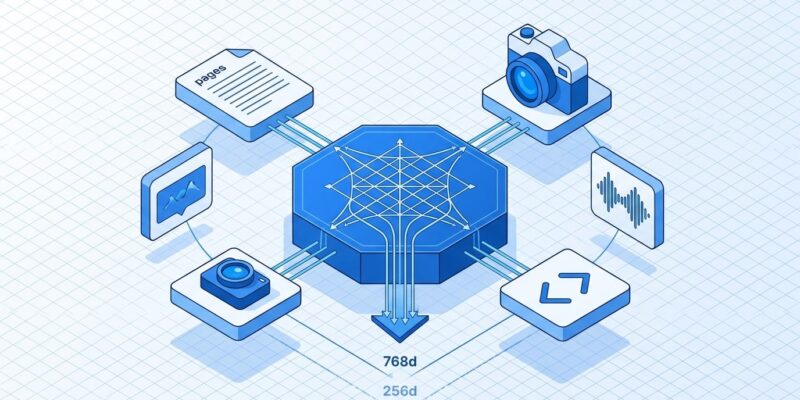
The headline capability is cross-modal retrieval: query with text, get back a matching image. Query with an image, retrieve a related audio clip. All from one model, no separate pipelines, no embedding space mismatch between modalities.
EmbeddingGemma 2 achieves this through modular encoders that all project into a shared 768-dimensional space. The architecture stacks on demand:
- Text/code encoder: 270M parameters, 8,192-token context window
- Vision encoder: +170M parameters (images, PDFs, video frames)
- Audio encoder: +300M parameters (raw audio ingestion)
You only load what you need. Text-only deployment uses 191MB of active RAM. The full multimodal model uses 567MB — numbers Google confirmed on a Pixel 11 Pro. For context, that is the retrieval layer of your entire RAG pipeline fitting inside a mid-tier Android phone.
Getting Started: Three Lines to Multimodal Search
EmbeddingGemma 2 ships with first-class sentence-transformers integration. One install, then encode across modalities:
pip install -U "sentence-transformers[image,audio,video]" transformersLoad only the modalities you actually use — memory stays proportional:
from sentence_transformers import SentenceTransformer

# Text-only: 270M params, ~191MB RAM
model = SentenceTransformer(
    "google/embeddinggemma-2",
    config_kwargs={"vision_config": None, "audio_config": None}
)

# Full multimodal: 740M params, ~567MB RAM
model = SentenceTransformer("google/embeddinggemma-2")
Cross-modal retrieval works identically to single-modality search — the shared vector space handles the rest:
image_emb = model.encode({"image": "product_photo.jpg"})
audio_emb = model.encode({"audio": "customer_call.wav"})
query_emb = model.encode("damaged packaging complaint", prompt_name="SearchQuery")

# Compare a text query against image and audio embeddings
print(model.similarity(query_emb, image_emb))
print(model.similarity(query_emb, audio_emb))
Use prompt_name="SearchQuery" for queries and prompt_name="Document" for indexed content. The asymmetric prompting measurably improves retrieval quality.
Cutting Storage Costs with MRL
EmbeddingGemma 2 uses Matryoshka Representation Learning, which lets you truncate output vectors without retraining. One million 768-dimensional vectors require about 1.5GB of storage. Truncate to 128 dimensions and that drops to 250MB.
The quality trade-off matters here:
- 256 dimensions: ~95% retrieval quality, 3x storage reduction — the practical default for most production workloads
- 128 dimensions: ~90% for text/code, but drops to ~75% for cross-modal retrieval — avoid for multimodal production use
query_emb = model.encode(
    query,
    prompt_name="SearchQuery",
    truncate_dim=256,
    normalize_embeddings=True
)
256 dimensions is the sweet spot: meaningful storage savings with negligible quality loss on text and code. Drop to 128 only if storage constraints are severe and multimodal fidelity is not a requirement.
Benchmark Reality Check
On MTEB Code, EmbeddingGemma 2 scores 78.68 — a 9.92-point gain over EmbeddingGemma 1. For coding agents that index repositories locally, that is a meaningful improvement in retrieval precision on technical content.
One honest caveat: Google published benchmarks compare EmbeddingGemma 2 only against its predecessor, not OpenAI text-embedding-3, Cohere embed-v4, or Voyage models. The claim of best-in-class among sub-1B multimodal embedders is plausible — most sub-1B models handle one or two modalities, not five — but it has not been independently verified against named alternatives. Treat the numbers as directional until the broader community runs comparisons on shared benchmarks.
What to Build With It
The practical use cases that were not viable before:
- Privacy-first enterprise RAG: Legal, healthcare, and finance teams handling sensitive documents can run the full retrieval layer on-prem without sending anything to a cloud embedding API.
- Coding agent memory: Index an entire codebase locally, retrieve relevant files and functions without loading everything into context. The MTEB Code gains make this more precise than EmbeddingGemma 1.
- Multimodal document search: Legal depositions with embedded photos, product catalogs with images, support tickets with screenshots — index and retrieve across the full content, not just extracted text.
- Local media libraries: Search photos with text queries, find audio clips by semantic description. Community testers reported 4 image embeddings/second and 6 audio embeddings/second on an M3 Pro.
The Gotchas
Three practical friction points before you ship: audio input requires 16kHz mono preprocessing — most real-world audio files will need conversion. Image inputs in sentence-transformers must be PIL objects or local file paths, not URLs. And for domain-specific audio classification tasks (financial calls, medical transcription classification), specialized models may still outperform the general-purpose audio encoder.
Available Now
EmbeddingGemma 2 weights are on Hugging Face and Kaggle under Apache 2.0. The model runs on vLLM, Ollama, LMStudio, and SGLang for server deployment, and via LiteRT for on-device Android and iOS. Google’s developer guide covers the full integration surface.
If your RAG pipeline is still text-only, this is the migration path to multimodal retrieval that does not require a new cloud vendor or a GPU cluster. A model that fits in 567MB and retrieves across five modalities has a reasonable shot at becoming the default embedding layer for privacy-conscious developer stacks.