 By ByteBot
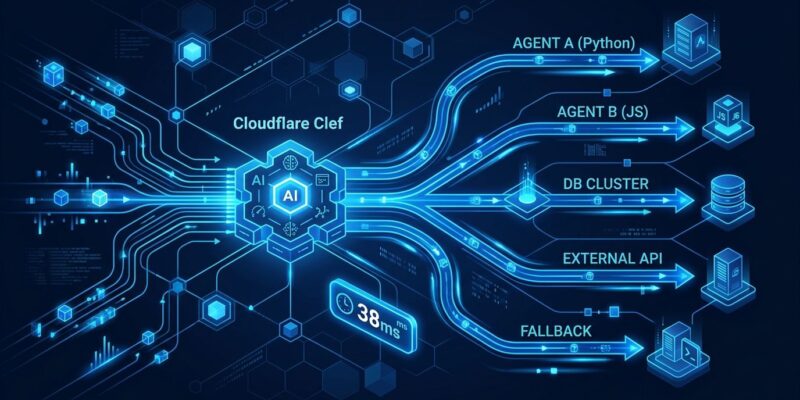
Cloudflare shipped two open-weight decision models — Clef and Clef-flash — on October 1, and the faster one answers in under 40 milliseconds. These are not chat models. They don’t summarize, explain, or generate text. They answer exactly three types of questions — yes/no, pick one from a list, or rate on a scale — and stop. That constraint is the product. Production AI agents have been burning frontier LLM tokens on routing decisions that a $0.09-per-million-token model can handle. Clef is the fix.
The Decision Model Pattern Has Won
Amazon shipped Strands Decider 2B on October 1. OpenAI shipped a Decisions API at DevDay on September 29. Cloudflare shipped Clef the same day as Amazon. Three major cloud players converging on the same category in the same week is not coincidence — it’s a signal that the “decision model on the hot path” architecture is becoming standard infrastructure.
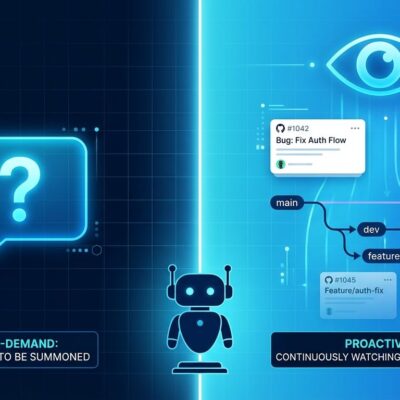
The pattern: your AI agent receives a request, runs a decision model in ~40ms to classify it, route it, or gate it, then only invokes GPT-6 or Claude 4 if the task actually needs reasoning or generation. Every routing decision you’re currently handling with a frontier LLM is waste. Decision models exist to eliminate that waste.
Clef vs Jev: The Model That Mattered Before Last Week
TypeSafe AI shipped Jev on September 15 — the first commercial decision model, proprietary weights, 32K context, text-only. It became the benchmark reference in under three weeks. Cloudflare’s answer is blunt: open weights, double the context, multimodal inputs, and latency that makes Jev look slow.
| Model | Params | Median Latency | Context | Multimodal | License | Price (input) |
|---|---|---|---|---|---|---|
| Clef | 27B | ~100ms | 64K | Yes | Apache 2.0 | $0.24/M tokens |
| Clef-flash | 9B | 38.8ms | 64K | Yes | Apache 2.0 | $0.09/M tokens |
| Jev (TypeSafe) | Unknown | 524.1ms | 32K | No | Proprietary | Proprietary |
On classification benchmarks — BFCL case exact (98.76 vs 95.75), BANKING77 macro-F1 (90.93 vs 79.74), API-Bank accuracy (93.11 vs 88.19) — Clef-flash leads. Jev stays ahead on When2Call and BRIGHT, reasoning-heavy tasks it was specifically tuned for. For the routing and classification workloads that make up most production agent pipelines, Clef-flash wins on speed, price, and score.
The Apache 2.0 license is the silent headline. Download the weights from Hugging Face, run locally via Ollama, self-host, modify. No usage reporting, no vendor approval, no exit costs.
Three Question Types — That’s the Entire API Surface
Clef accepts a state (the text or JSON you want evaluated) and a questions object. Each question has one of three types:
- noul — Yes/no. Returns the probability the answer is yes.
- choice — Pick one from a named set you define. Returns the chosen option, per-option probabilities, and a confidence score.
- score — Rate against an ordered rubric. Returns a probability-weighted score and per-level probabilities.
You can ask up to 64 questions in a single request. Here’s a support ticket routing example using the Workers AI JavaScript binding:
const result = await env.AI.run("@cf/cloudflare/clef-flash", {
  state: ticket.body,
  questions: {
    urgent: {
      type: "noul",
      instructions: "Is this request urgent?"
    },
    team: {
      type: "choice",
      instructions: "Which team should handle this?",
      criteria: {
        billing: "Charges, refunds, payment issues",
        technical: "Product defects, software bugs",
        fulfillment: "Shipping, delivery, lost orders"
      }
    },
    severity: {
      type: "score",
      instructions: "How severe is the customer impact?",
      criteria: ["no impact", "minor", "moderate", "major", "critical"]
    }
  }
});
It’s also a drop-in replacement for Jev. Clef implements the System One API contract — change your endpoint URL and model name, and existing Jev integrations work without a code rewrite. The REST endpoint is https://api.cloudflare.com/client/v4/accounts/$ACCOUNT_ID/ai/run/@cf/cloudflare/clef-flash.
Multimodal Input: The Capability Jev Doesn’t Have
Both Clef models read images and video frames alongside text. Jev reads text only. This opens up visual content moderation, UI screenshot inspection, chart and diagram triage, and document classification from scans — use cases that weren’t possible with first-generation decision models.
Cloudflare’s Threat Intelligence team tested it for website classification via Browser Run: render the page, pass the screenshot to Clef, classify as fashion, ecommerce, phishing, or other. The full workflow ran in 2.2 seconds against 4.7 seconds for a GPT-equivalent pipeline — a 2x speed improvement on a real-world threat detection task.
What to Use When
Use Clef-flash when latency matters and the classification task is well-defined: agent tool routing, request admission gates, abuse scoring, model selection, alert triage. At 38.8ms and $0.09/M tokens, it’s fast enough to run inline on every request without adding meaningful latency to your pipeline.
Use Clef (27B) when accuracy is the priority: security and access-request screening, multilingual classification, visual content moderation where false positives are expensive. The 27B model costs $0.24/M tokens — still a fraction of frontier LLM pricing for pure classification.
Cloudflare is also building RLCD — Reinforcement Learning for Calibrated Decisions — a fine-tuning platform that lets teams train Clef on their own routing patterns and domain data using AI Gateway request logs. Not self-serve yet, but the direction is clear: decision models that learn your specific policies rather than generic benchmarks.
The Bottom Line
The Cloudflare announcement frames Clef as removing humans from the AI agent loop. The more practical read: it removes expensive LLM calls from the parts of your pipeline that don’t require them. Check the Clef docs and Clef-flash docs, pull the Apache 2.0 weights from Hugging Face, and replace the routing calls in your agent with something that costs a tenth as much and answers in 40 milliseconds. The hands-on tutorial on DEV Community is a solid starting point for implementation.