 By ByteBot
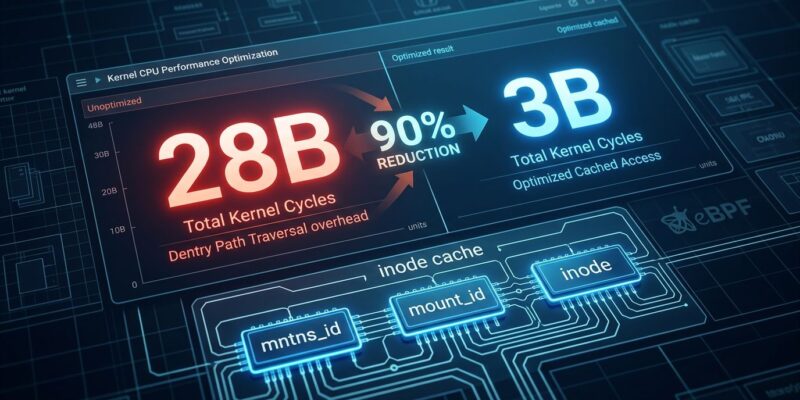
A developer added one cache to their eBPF security agent and cut kernel CPU cycles by 90%. Not 9%. Ninety. In a benchmark of 200,000 repeated file opens, their agent dropped from 28 billion kernel cycles to 3 billion. The technique is decades old — SELinux has done it since 2001. However, if you’re building an eBPF security tool today, you’re probably still rediscovering it from scratch.
Nathan Naveen’s deep-dive landed on Hacker News this morning and has been climbing the front page since. It’s worth reading not because eBPF memoization is surprising, but because getting it right in kernel space is genuinely non-obvious — and the failure modes are security bugs, not just performance ones.
The Problem: Paths Are Expensive
When an eBPF security agent enforces file path policies — allow writes to /var/app, deny exec from /tmp — it hooks into the kernel’s Linux Security Module (LSM) interface on every file open. For each open, it reconstructs the full file path by walking up the dentry tree, checks each parent directory against its policy list, and combines the results into an allow/deny decision.
That work repeats identically on every single open. Open the same file 1,000 times, walk the dentry tree 1,000 times. On a busy build system or CI runner opening hundreds of thousands of files, this adds up fast. In Naveen’s benchmark, it consumed 28 billion kernel cycles — enough to show up as measurable overhead in production profiling.
The Fix: Cache by Inode
The fix is conceptually simple: once you’ve computed the policy decision for a given file, cache it by inode. Next time that file opens, return the cached answer and skip the path walk entirely. Moreover, this is the same strategy SELinux uses in its Access Vector Cache (AVC), built into the kernel since the early 2000s. The difference is that eBPF developers are on their own — there’s no built-in AVC for BPF programs. You build it yourself using a BPF map.
Naveen used a BPF_MAP_TYPE_LRU_HASH: a hash map that automatically evicts least-recently-used entries when full, capped at 10,000 entries. That part is straightforward. What’s not straightforward is the cache key.
The eBPF Cache Key Is the Hard Part
Your instinct might be to key the cache by inode number alone. That’s wrong — and dangerously wrong in containerized environments. Inode numbers are only unique within a specific mounted filesystem. The same inode number can exist simultaneously in two different mounted trees referring to completely different files. In a containerized system with dozens of namespaces, keying by inode alone means a cached policy decision from one container could be served to another.
The correct key needs three fields:
struct inode_cache_key {
    u64 mntns_id;    // mount namespace ID
    u64 mount_id;    // specific mounted filesystem
    u64 inode;       // inode number within that mount
};
The mount namespace ID scopes the cache to a specific container or process namespace. The mount ID distinguishes between different filesystems that happen to have the same inode numbers. Only with all three fields together do you get an identifier that uniquely refers to a specific file across namespaces and mount trees. Without any one of these, you’re not looking at a performance problem — you’re looking at a security vulnerability.
One Edge Case That Matters: Hardlinks
Hardlinks let multiple paths share a single inode. If /data/allowed.txt and /restricted/blocked.txt are hardlinks pointing to inode 42, caching the policy for inode 42 will give the wrong answer for one of them.
The implementation handles this by bypassing the cache whenever the link count exceeds 1:
if (nlink != 1) {
    // Skip cache for hardlinked inodes — correctness over performance
    return false;
}
That means hardlinked files always take the slow path. The cache hit rate drops for those inodes, but the policy decision is always correct. It’s a sensible trade-off: accept partial coverage rather than risk a security misclassification.
The Results
On 200,000 repeated file opens, the numbers speak clearly:
- Kernel cycles: 28 billion → 3 billion (-89%)
path_check_callbackstack presence: 63.7% → ~0.02%tail_call_security_checkpresence: 89.2% → ~0.02%
The overhead functions essentially vanished from the profile. Furthermore, that’s the shape of a well-targeted optimization — one hot path eliminated, everything else unchanged. The Hacker News discussion is worth reading alongside the post itself.
The Reality Check
The HN crowd offered useful qualifications. First, 90% applies to the specific case of repeatedly opening the same files — a benchmark that models build systems and test runners well, but not all workloads. A web server serving diverse dynamic paths would see much lower cache hit rates and correspondingly smaller gains. Second, the post measures CPU cycles but not memory: 10,000 cache entries is negligible in RAM terms, but the principle matters as you scale the cache up.
The most common comment: “SELinux’s AVC has done this for decades.” That’s true. The point isn’t that memoization is a new idea — it’s that applying it correctly in an eBPF program requires getting the cache key right, and getting the cache key right requires understanding namespaces, mount trees, and hardlinks. The BPF_MAP_TYPE_LRU_HASH documentation tells you how to build the map; nobody tells you how to design a correct key for a security context. Datadog’s engineering team learned the same lesson — do aggressive in-kernel filtering early, reduce round-trips to user space.
When to Use This Pattern
This is worth applying when your eBPF agent enforces path-based file policies, your workload opens the same files repeatedly (builds, servers, databases), and you’ve profiled and confirmed dentry traversal shows up in your kernel CPU profile.
If you’re building a custom eBPF security agent today, this cache pattern should be in your initial design, not discovered later during a production incident. The Linux LSM BPF documentation covers the hook interface; Naveen’s post covers the optimization. Read both before you ship. And check your hardlink handling — that edge case will find you eventually.