 By ByteBot
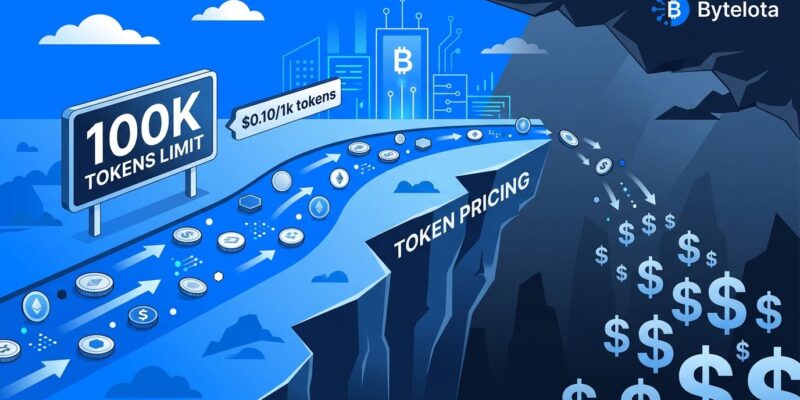
Anthropic shipped Claude Haiku 5.5 on October 7 with a headline that is hard to argue with: 90% cheaper than Haiku 4.5. What the announcement buries is that the new tokenizer produces roughly 30% more tokens from the same text — and prompts over 100,000 tokens pay 5x more per input token than prompts under it. A workload that clocked in at 78,000 tokens on Haiku 4.5 now runs at 101,400 and crosses into the expensive tier. Same work, 412% higher bill.
The Cliff, Explained
Haiku 5.5 uses a tiered pricing model with a hard threshold at 100,000 tokens per request. Under that line: $0.10 per million input tokens. Over it: $0.50 per million — a 5x jump. Output tokens follow the same pattern ($0.50 vs $2.50 per million).
That threshold would be manageable if the tokenizer stayed the same. It did not. Haiku 5.5 uses the tokenizer introduced with Claude 4.7, which encodes the same text in roughly 30% more tokens than Haiku 4.5 used. A prompt that measured 77,000 tokens on the old model now comes in around 100,100 tokens on the new one — just enough to clear the cliff.
The cost impact is not subtle. In one real-world example, 10,000 contract review requests at 76,000 old-count tokens cost $111.80 on Haiku 5.5. Move those same requests up to 78,000 old-count tokens — 101,400 new — and the bill is $572.00. Anthropic says roughly 90% of Haiku requests historically fell under 100,000 tokens. That percentage will be lower on 5.5 before you do any tuning.
The fix: audit your longest prompts now, before switching. Trim or chunk anything that was near 77,000 tokens on Haiku 4.5. The official Claude Haiku 5.5 announcement includes tokenizer comparison details.
Five Breaking Changes That Will Error Your Code
If you drop claude-haiku-5-5 into your existing Haiku 4.5 integration without changes, five things will fail immediately:
- Manual thinking budgets removed. The
budget_tokensparameter returns a 400. Replace it with"thinking": {"type": "adaptive"}and control depth viaoutput_config: {"effort": "medium"}. - Sampling parameters removed. Non-default
temperature,top_p, andtop_kall return 400 errors. Omit them entirely. - Assistant prefill removed. Final assistant turns in your message array will fail. Remove any prefill logic.
- Computer use tool renamed. The
computer_20250124tool returns errors. Usecomputer_toolset_20260801on Claude API and Google Cloud, orcomputer_20251124on Amazon Bedrock. - New refusal stop reason. Haiku 5.5 can return
stop_reason: "refusal"instead of completing a response. There is no server-side fallback — your code must handle it.
The updated request format:
{
  "model": "claude-haiku-5-5",
  "max_tokens": 16000,
  "thinking": { "type": "adaptive" },
  "output_config": { "effort": "medium" },
  "messages": [{ "role": "user", "content": "..." }]
}
For high-volume classification where you want minimal reasoning overhead, set effort to low. The model skips thinking on simple requests, cutting both latency and tokens. The full list of breaking changes is documented in the Claude platform release notes.
Computer Use: From 15.7% to 72.4%
Buried under the pricing story is a benchmark worth paying attention to. On OSWorld 2.1 — the standard offline computer use evaluation — Haiku 5.5 scores 72.4%. Haiku 4.5 scored 15.7% on the same test. That is not an incremental improvement. It is a different class of model for agentic desktop and browser work.
The Python and TypeScript SDKs now include beta tool classes for computer use and browser use. The old approach required building your own tool loop; the new SDK classes handle the loop, URL and file policies, and approval callbacks. You subclass ComputerTool or BrowserTool and implement one method per action.
The practical implication: Haiku 5.5 is now viable for browser automation workflows that Haiku 4.5 would have handled badly. At $0.10 per million input tokens for short-context use cases, the economics of running computer-use agents at scale change considerably.
When to Migrate Now vs Audit First
Migrate immediately if your workloads are short-context and high-volume: classification, routing, summarization, ticket triage, extraction. These are the use cases Haiku 5.5 was built for, and the 90% price cut is real for them.
Audit before migrating if any of your prompts were running over 60,000 tokens on Haiku 4.5. The tokenizer inflation puts anything in that range at risk of crossing the 100K threshold. Measure first.
Do not migrate if your workload requires complex agentic coding. Haiku 5.5 hits 39.2% on Terminal-Bench 4.0; Sonnet 5.5 hits 70.6% on the same benchmark. The cost savings do not justify the capability gap for coding agents.
The detailed pricing breakdown with worked examples is worth reading before you touch your production configuration. Haiku 5.5 is a genuinely better model — the savings are real for the right workloads. Just do not let the headline do the math for you.